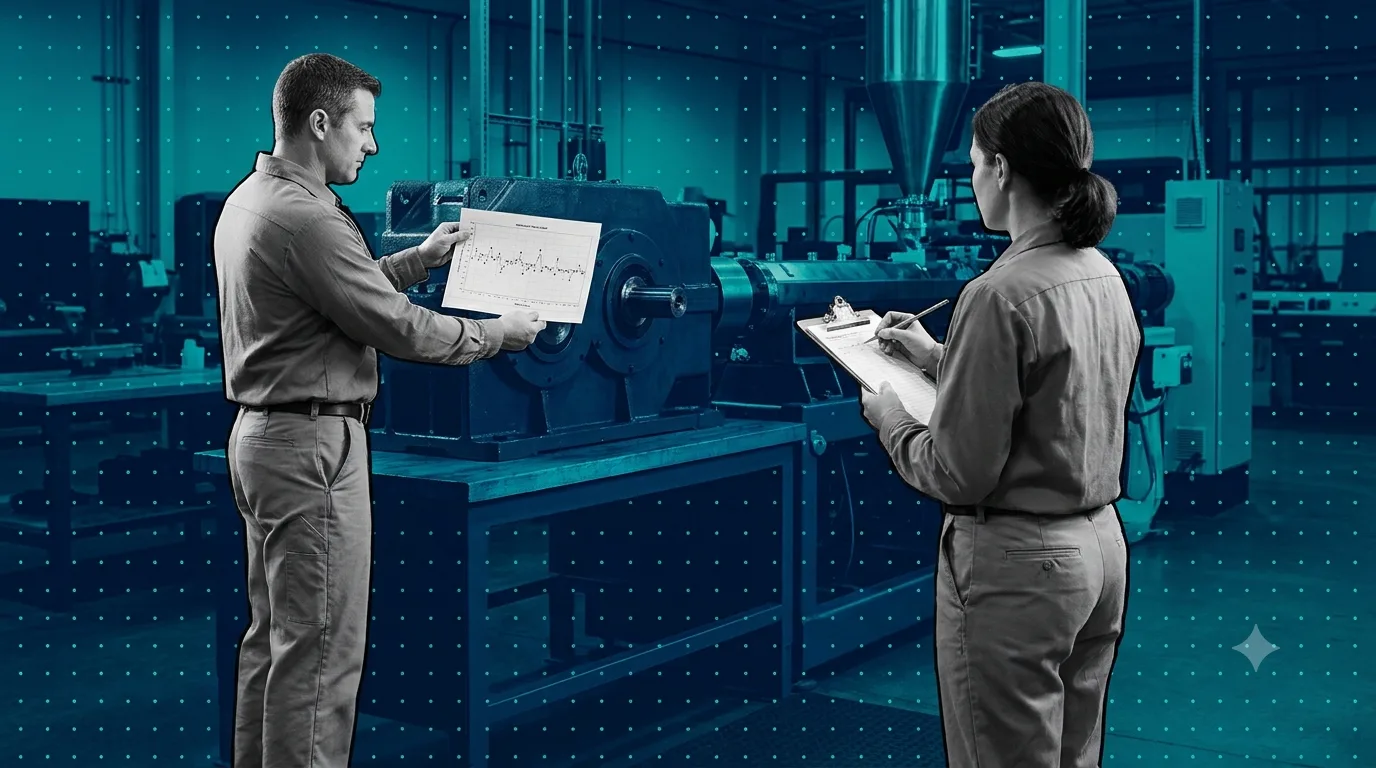
Predictive maintenance (PdM) uses condition data, and the way that data is trending, to forecast when an asset will reach failure, so the repair can be planned before it does. Condition-based maintenance acts when a reading crosses a limit. Predictive maintenance estimates when it will. Both only pay off if the warning turns into a planned job.
Most writing about predictive maintenance is about the technology: sensors, data platforms, machine learning. That's the visible part. What decides whether a PdM program works is less visible. You need to know which assets deserve it, you need failure records a forecast can learn from, and you need someone who turns an alert into a work order with a date on it.
This guide covers what predictive maintenance actually forecasts, how it compares with preventive and condition-based maintenance, which assets justify it, seven questions to answer before you buy any monitoring technology, and a worked example on the main gearbox of an extrusion line.
What predictive maintenance is
Predictive maintenance is a strategy where the timing of the work comes from the asset's measured condition and a forecast of how that condition will change. Instead of servicing a gearbox every so many months, or waiting until it fails, you measure something that changes as a failure develops (vibration, wear particles in the oil, temperature), watch the trend, and schedule the repair for before the trend reaches failure.
The data can come in two ways:
- Periodic. A technician takes readings on a route with a handheld vibration meter, an oil sample bottle or a thermal camera. The trend is built one reading at a time.
- Online (continuous). Sensors fixed to the asset send readings all the time. The trend is always current.
Online monitoring catches faults that develop between route visits, but it costs more per asset and produces far more data to look after. Many programs use both: routes for most assets, continuous monitoring for the few that justify it.
How the forecast itself is made varies, from a simple trend line projected forward to statistical and machine learning models trained on past readings and failures. Either way, it can only learn from failures that were measured and recorded.
A note on terms. Some sources use "condition-based maintenance" and "predictive maintenance" interchangeably, or treat PdM as one form of CBM. Others separate them: CBM reacts when a reading crosses a limit, and PdM forecasts when it will. Both readings are common. This guide uses the second, because the difference changes how you plan the work. The international standard on the forecasting side is ISO 13381-1:2025, which calls it prognostics and gives guidance for developing a prognosis process.
What predictive maintenance actually forecasts
Most failures don't happen instantly. There's a point P where a developing failure first becomes detectable, such as a vibration change, a temperature rise, or metal particles showing up in the oil. Later there's a point F where the asset actually fails. The time between them is the P-F interval, and our reliability-centered maintenance guide explains how it sets inspection intervals.
A predictive maintenance forecast is an estimate of how much of that interval is left. That's the difference between the two approaches:
- Condition-based maintenance says: "The reading has crossed the limit. Act now."
- Predictive maintenance says: "At the current rate, the reading will cross the limit in a few weeks. Book the repair for the planned shutdown before then."
That difference is the whole value of the word "predictive": a planned date instead of an alarm. The repair still happens either way. What changes is whether it happens on a night shift with whatever parts are in the store, or as planned maintenance in a window with the parts, the people and the procedure ready.
A forecast is an estimate, not a promise. Trends change speed, loads change, and a model can be wrong. That's why a predictive program needs a way to check each forecast against what the technician actually found, which comes up again below.
Predictive maintenance techniques
The common condition monitoring techniques, and what each one is good at catching:
- Vibration analysis. Bearing defects, imbalance, misalignment, looseness and gear tooth wear in rotating equipment.
- Oil analysis. Wear metals and particles from gears and bearings, contamination such as water or dirt, and the lubricant itself breaking down.
- Infrared thermography. Hot spots: loose or overloaded electrical connections, overheating bearings and motors, failed insulation.
- Ultrasound. Compressed air and gas leaks, early lubrication problems in bearings, valves passing, and electrical arcing.
- Motor current analysis. Electrical faults in motors, such as broken rotor bars, and some mechanical problems in the driven load that show up in the current.
Process data (pressure, flow, temperature, power draw) also trends and can be used the same way. Our condition-based maintenance guide has a table that pairs common failure modes with their warning signs and how each one is checked.
Searches for "the three types of predictive maintenance" have no standard answer. Vendors list three, five or six types, grouped in different ways. The techniques above are the ones nearly every list includes.
Predictive vs preventive maintenance (and where condition-based fits)
| Preventive | Condition-based | Predictive | |
|---|---|---|---|
| Trigger | Calendar or usage | Reading crosses a limit | Forecast of when it will |
| Data needed | Interval and checklist | Readings against limits | Trended readings plus failure history |
| What you get | Work at fixed intervals | An alarm to act on | A date to plan around |
| Setup effort | Low | Moderate | High |
| Best for | Age-related wear, no warning sign | Detectable warning, slow to develop | Critical assets, fast or irregular warning |
These aren't rival philosophies. A typical plant runs all of them, plus deliberate run to failure, on different assets. Preventive maintenance stays the backbone for wear that gives no practical warning. Condition-based maintenance covers the larger group of assets that do give warning. Predictive maintenance sits on top, on the short list where a planned date is worth the extra effort. The condition-based maintenance guide covers where its line with predictive falls in more detail, and types of maintenance puts all four side by side.
Which assets justify predictive maintenance
This is a decision made asset by asset. Choosing the right task for each failure mode is a deeper job, and that's what reliability-centered maintenance is for. At the asset level, a rough guide:
| Strategy | Fits when | Example |
|---|---|---|
| Run to failure | Cheap, non-critical, spare on the shelf | Gauge on a non-critical branch line |
| Preventive (time-based) | Age-related wear with no practical warning sign | Filters, lubrication points |
| Condition-based route | Detectable warning, slow enough for periodic checks, moderate consequence | Utility pump with a standby |
| Predictive | High consequence, warning that develops fast or unpredictably, enough history to trust a trend | Main drive gearbox on a line with no standby |
Run to failure only works when it's chosen on purpose, with the spare and the breakdown maintenance response ready. Most assets in a plant land in the first three rows. Predictive maintenance is for the few at the top of the criticality list, where an unplanned stop is expensive and a periodic route could miss the warning.
Is your plant ready? Seven questions to answer before buying predictive maintenance technology
The questions are in the order you'd build the answers. Most plants can't say yes to all seven yet. That isn't a failing. It's sequencing, and each answer you put in place pays off on its own, with or without predictive maintenance.
1. Do you know which assets are critical?
Ready looks like: every asset has a criticality ranking based on what its failure does to safety, quality and output. A simple A/B/C ranking is enough. Without it, monitoring gets bought for the assets someone happens to worry about.
2. Does your PM program actually run?
Ready looks like: preventive work gets done when it's due, and when it isn't, it's visible to someone. If PM work orders slip quietly into deferred maintenance, predictive alerts will slip the same way.
3. Do you already run condition checks on those assets?
Ready looks like: your critical assets are on an inspection route, and the readings are recorded against each asset rather than kept on paper. Predictive maintenance is condition-based maintenance with a forecast added, so start with CBM.
4. Is your failure history usable?
Ready looks like: every breakdown work order records the failure mode and cause, using the same codes each time. "Repaired motor" teaches nothing. "Drive-end bearing, lubrication failure" does. A model can only learn from the failures you recorded, and so can a reliability engineer. The same history gives you MTBF per asset and MTTF per part.
5. Does the failure you want to predict give a measurable warning that trends?
Ready looks like: you can name the failure mode and the measurement that changes before it. Some failures give no usable warning, and no amount of monitoring will forecast them.
6. When an alert lands at 2am, who owns it?
Ready looks like: a named person or role receives each alert, decides what it means, and turns it into a work order. A maintenance planner then schedules it into a planned window. If an alert can sit in an inbox until someone notices, the forecast's lead time is wasted.
7. Will you record what the technician found?
Ready looks like: at every repair triggered by a forecast, the technician records the as-found condition. That's how false alarms get counted, missed failures get noticed, and limits get adjusted. Without it, nobody can say whether the program works.
Not sure your failure history is good enough? Work out MTBF for one critical asset from its breakdown records and see what's missing.
Open the MTBF calculatorPredictive maintenance example: an extrusion line's main gearbox
Illustrative example, not a customer case. A plastics plant runs an extrusion line whose main drive gearbox sits between the motor and the screw. There's no standby. If the gearbox fails, the line stops, and a replacement isn't something the plant keeps on the shelf. That makes it an obvious candidate. Here's how its maintenance could move toward predictive, one stage at a time.
Stage 1: calendar oil changes and a breakdown history
Today the gearbox gets an oil change on a fixed interval, and the plant has a few past breakdowns on record. The first job is to make that history useful: go back through the breakdown work orders, code each one with its failure mode (bearing, gear tooth, seal, lubrication), and start recording new ones the same way.
Stage 2: a condition route
Next, the gearbox goes on a monthly route: a vibration reading at each bearing housing and an oil sample sent for analysis. Every reading is recorded against the asset. This is plain condition-based maintenance. When a reading crosses its limit, the gearbox gets inspected.
Stage 3: continuous monitoring and a trend
After enough route readings, and a couple of recorded failures to compare them against, the plant fits continuous vibration monitoring and starts trending the data. The change isn't the sensor. It's that the planner now gets a date range to aim for instead of a sudden alarm, and can line the repair up with the next planned shutdown.
The loop: forecast, work order, repair, as-found record
When the trend shows a bearing defect developing, the loop runs like this:
- Forecast. The trend says the reading will reach its limit before the shutdown after next.
- Work order. The reliability technician raises a work order against the gearbox, with the forecast attached.
- Plan. The planner books it into the next shutdown, orders the bearings and assigns the crew.
- Repair. The gearbox is opened on schedule, and the technician records what they found: the bearing condition, photos, and whether the damage matched the forecast.
- Review. If the bearing was where the trend said, the forecast held. If it was in better shape, the limit may be too tight. If it was worse, the limit or the monitoring needs to change.
Step 5 is what most programs skip. It's also the only way to know whether the forecasts can be trusted the next time.
How to implement predictive maintenance, step by step
- Pick one to three critical assets. Use your criticality ranking. Choose assets where a failure is expensive and the failure mode gives a warning.
- Fix the failure history first. Set up consistent failure-mode codes and make sure every breakdown on those assets records one.
- Run condition routes and record the readings. Use checklists for the route so readings are taken the same way each time.
- Pilot monitoring on one asset. Start with the asset whose failure history and route data are strongest.
- Define the alert-to-work-order path before the sensors arrive. Decide who receives alerts, how they become work orders, and how the planner schedules them.
- Review each forecast against the as-found findings. Count the forecasts that held, the false alarms and the misses.
- Expand only when the pilot's forecasts held up. Add assets one at a time, and keep the preventive and condition-based programs running underneath.
None of these steps names a technology. The technology choice matters, but it comes after steps 1 to 3, and those steps are where most programs that stall actually stall.
Where a CMMS helps
A CMMS doesn't predict anything. It's where a forecast becomes a planned work order with a date, parts, a checklist, and a recorded finding that confirms or corrects the prediction. It also holds most of what the readiness questions above depend on. Our guide to what a CMMS is covers the basics.
In MachDatum, criticality sits on each asset record alongside the asset's full history, so the shortlist for monitoring comes straight from the asset register. Work order workflows can require a root cause when repair starts and downtime hours at close, and failure-mode lists can be set up as reference tables, so every breakdown is coded the same way. PM plans and inspection routes are auto-dispatched with versioned checklists attached, overdue work surfaces in the PM list, and escalation rules pull in the manager when jobs slip.
When an alert arrives, whoever owns it raises a work order against the asset from the mobile app, by scanning the asset's QR tag and attaching a photo. A dedicated work order type can require the as-found condition before the job closes, which is how you measure whether forecasts are right. MTBF, MTTR and downtime by asset come from the same work order data, so you can see whether the program is moving the maintenance KPIs that matter.
If your machines are monitored with ThingConnect, MachDatum's sister product, its condition signals and reason-coded stops can open work orders in MachDatum automatically. That covers CNC machines connected to ThingConnect; the ThingConnect CMMS integration page lists what each event creates.
We're onboarding our first group of manufacturing teams now. If you want the failure history, the routes and the forecast-to-work-order path in one place before you add monitoring, see how MachDatum CMMS handles assets, PM plans and work orders.