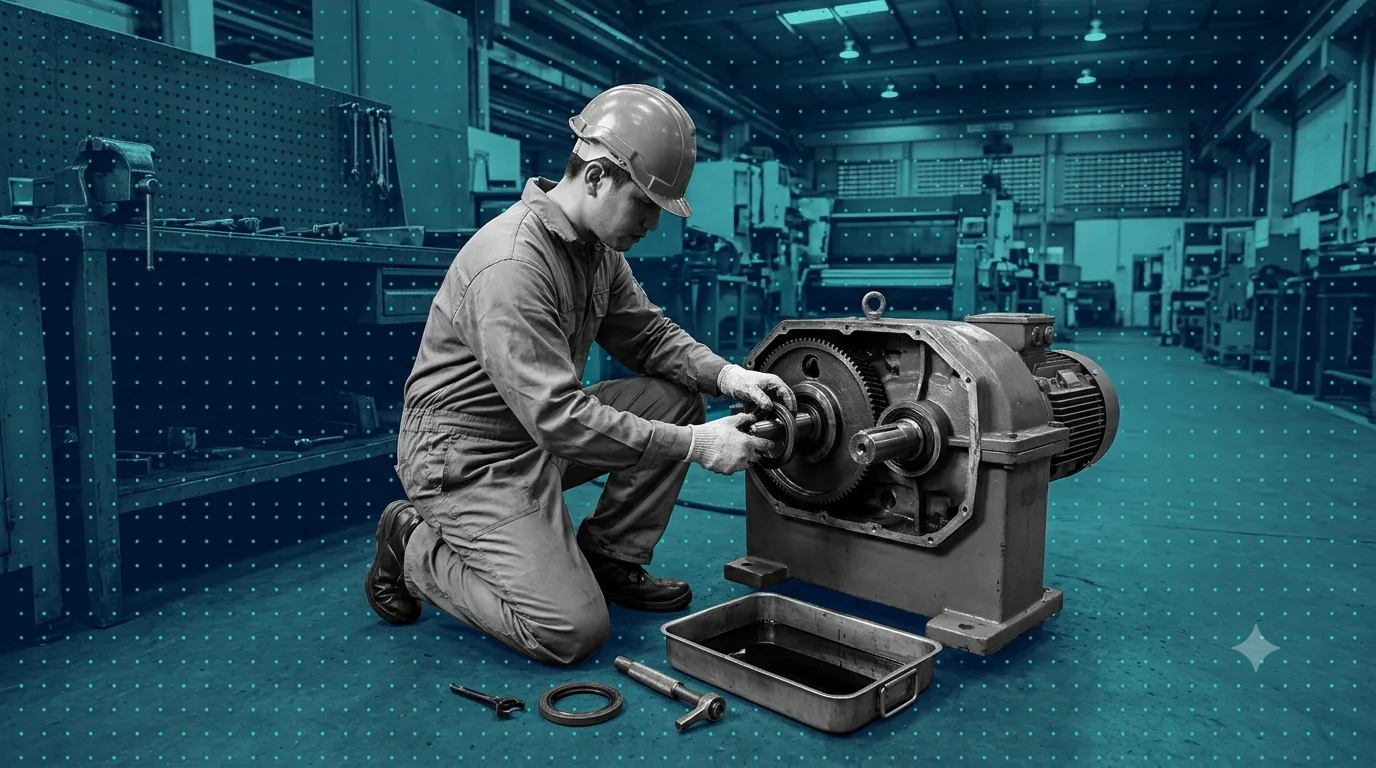
Condition-based maintenance (CBM) means doing maintenance when a measured sign of wear says it's needed, not on a fixed date. You pick a condition that warns of failure, such as vibration, temperature, oil condition or a leak. You check it often enough to catch the warning, and you act before the asset fails.
Most explanations of CBM jump straight to installed sensors and software. In most plants, though, CBM is a technician on a weekly route with a vibration pen, an infrared thermometer and a notebook. The hard part isn't the sensing. It's deciding the limit, how often to check, and what happens when a reading crosses the line.
This guide covers those decisions, then works through one inspection route from the first reading to the finished repair.
What condition-based maintenance is
In condition-based maintenance, the trigger for work is the measured condition of the asset. A bearing gets replaced because its vibration has risen, not because 12 months have passed. A filter gets changed because the pressure drop across it says it's loaded, not because the quarter ended.
Two terms get mixed up here:
- Condition monitoring is the measuring: taking vibration readings, thermal images, oil samples.
- Condition-based maintenance is the maintenance decision built on those measurements: what limit triggers action, and what action follows.
You can monitor a lot and still not be doing CBM, if nobody acts on the readings. CBM can run on online measurements (sensors fixed to the machine) or offline ones (a person with a handheld tool on a route). Both count.
In reliability terms, CBM is an on-condition task. Our reliability-centered maintenance guide explains why RCM picks it first whenever a failure gives a detectable warning. You'll also see the term CBM+ (condition-based maintenance plus). That's the US Department of Defense's name for its CBM program across military equipment, which adds reliability analysis and data tools to the same basic idea.
Condition-based maintenance examples
| Failure mode | Warning sign | How it's checked |
|---|---|---|
| Rolling bearing wear | Rising vibration, then heat | Vibration pen or analyzer |
| Loose electrical connection | Hot spot on the terminal | Infrared thermography |
| Gearbox wear | Wear metals in the oil | Oil sample and analysis |
| Compressed-air leak | High-frequency hiss | Ultrasound detector |
| Filter loading | Pressure drop across it | Differential-pressure gauge |
| Belt wear or slack | Cracks, glazing, low tension | Visual check, tension gauge |
| Motor winding breakdown | Falling insulation resistance | Insulation tester, current check |
| Seal wear | Weeping, then dripping | Visual check on a daily round |
None of these needs a sensor installed on the machine. Every one can be done on a route.
How CBM works: the four decisions
Every CBM task comes down to four decisions:
- What to measure. The condition that changes before this failure mode happens.
- What limit means "act". The reading at which you stop watching and start planning a repair.
- How often to check. Often enough that the warning can't develop into a failure between two checks.
- What happens when the limit is crossed. Who confirms it, what work gets raised, and how fast.
Most CBM programs that fail don't fail on decision 1. They fail on decisions 2 to 4: limits nobody believes, routes that slip, and readings written down and never acted on.
ISO 17359, the ISO guideline for setting up a condition monitoring program for machines, covers the same ground: alert and alarm criteria, baseline data, and deciding the maintenance action.
Setting the alarm limit
A limit has to come from somewhere. There are three usual sources, and you'll often use more than one on the same asset.
1. The OEM limit
If the manufacturer's manual gives a limit (a maximum bearing temperature, a maximum discharge temperature, the red zone on a filter indicator), start there. The OEM knows the design.
2. A published severity standard
For vibration, the ISO 20816 series describes evaluation zones for machine vibration in four bands:
- Zone A: typical of newly commissioned machines
- Zone B: acceptable for unrestricted long-term operation
- Zone C: acceptable only for a limited period, so plan corrective action
- Zone D: severe enough to cause damage
The zone boundaries depend on the machine type, size and mounting. Use the part of the series that matches your machine, as a sanity check on your own limits.
3. Your own baseline plus trend
This is the most useful source, and the one most plants skip. Take readings when the asset is healthy, on the same measurement point, at the same load and speed. That's the baseline. From then on, change from baseline usually tells you more than the absolute number.
A gearbox that has always run quietly and has now doubled is telling you something, even if the reading is still inside the standard's acceptable zone. One that has always run a bit high and hasn't changed in two years probably isn't. Mark the measurement point on the housing, and take readings at the same load, or the trend means nothing.
Two levels, not one
- Watch: the reading is clearly above baseline but not alarming. Shorten the check interval, note it on the asset, and line up the parts and a planned stop.
- Act: schedule the repair within the time you have left before failure.
In the example route below, watch is set at 1.5 times the asset's baseline and act at twice the baseline, or the OEM limit if that comes first. Those are illustrative choices for the example, not a standard. Your own history should move them over time.
How often to check: the P-F interval
Most failures don't happen instantly. There's a point P where a developing failure first becomes detectable, and a later point F where the asset fails. The time between them is the P-F interval. Our RCM guide covers the concept in more detail in the P-F interval and how often to inspect.
For a route, the P-F interval sets the check frequency:
- A bearing whose vibration change shows weeks before it seizes can go on a weekly or fortnightly vibration route.
- A hydraulic hose that goes from a weep to a spray in days needs a daily check, and that's usually an operator's job on the start-of-shift round, not a technician's.
- A loose panel connection that heats slowly over months can be caught by a quarterly thermal survey.
A common practice is to check at about half the P-F interval. That puts at least one check inside the warning window and leaves time to plan the repair. It's a practice, not a law, and short or uncertain intervals call for more margin.
This is also why a skipped route is riskier than it looks. Miss one check on a short P-F interval, and the failure can go from undetected to broken in one step, the same risk our deferred maintenance guide describes.
A condition-based maintenance example: one weekly inspection route
Here's a worked route for the utilities and line drives of a packaging plant. It's an example route, not a recommendation for your assets. The assets, limits and frequencies are illustrative. The structure is what carries over.
What gets checked, with what, and by whom
| Asset | Condition checked | Tool | Who |
|---|---|---|---|
| Air compressor | Discharge temperature, oil condition | Panel gauge, oil sight glass | Technician |
| Conveyor gearbox | Bearing housing vibration, oil level and color | Vibration pen, sight glass | Technician |
| Conveyor drive motor | Bearing temperature | Infrared thermometer | Technician |
| Hydraulic power unit | Oil temperature, filter indicator, leaks | Gauge, filter indicator, visual | Technician (leaks: operator, daily) |
| Extraction fan | Vibration, belt condition | Vibration pen, visual | Technician |
| Main electrical panel | Hot spots on terminals | Thermal imaging camera | Contractor |
Where each limit comes from, and why that frequency
| Asset | Limit source | Frequency | Why that often |
|---|---|---|---|
| Air compressor | OEM manual | Weekly | Overheating and oil breakdown build over weeks |
| Conveyor gearbox | Own baseline, ISO 20816 as a check | Weekly | Bearing warning shows weeks ahead |
| Conveyor drive motor | OEM limit plus own baseline | Weekly | Bearing heat rises over weeks |
| Hydraulic power unit | OEM manual, indicator's red zone | Weekly (leaks daily) | Leaks can go weep to spray in days |
| Extraction fan | Own baseline, ISO 20816 as a check | Fortnightly | Non-critical, longer warning |
| Main electrical panel | Contractor's survey criteria | Quarterly | Connections loosen and heat slowly |
Notice the leak check. Its P-F interval is days, so it moves to the operator's daily round. One asset can carry checks at different frequencies.
One reading, from route to repair
Follow the conveyor gearbox through a few weeks:
- Baseline. When the gearbox was healthy, the technician took readings on the marked point on the output-shaft bearing housing at full line speed. That reading is written on the asset as its baseline, with watch at 1.5 times and act at twice.
- Week 1 to 6. Readings stay close to baseline. Nothing to do.
- Week 7. The reading comes in above watch. The technician notes it on the asset and the check moves from weekly to twice a week. The planner checks that a replacement bearing and seal kit are in stores.
- Week 8. The reading crosses act, and the oil looks darker than usual. The technician raises a corrective work order with the reading, a photo of the oil and the as-found condition.
- Planning. The last two readings suggest weeks of warning are left, not days. The planner books the bearing change into the weekend stop, five days out, instead of stopping the line mid-shift.
- Repair. The bearing comes out with spalling on the outer race. The technician records that on the work order as the failure mode, with a photo.
- After. A new baseline is taken on the rebuilt gearbox, because a new bearing won't read like the old healthy one did.
Step 6 is the one most plants skip, and it's what makes the next set of limits better. If the bearing had come out looking fine, the limit or the measurement method needs another look.
Are your inspection routes actually getting done on time? The PM compliance calculator shows how many are slipping.
Open the PM compliance calculatorWhat happens after a reading crosses the limit
Every reading that crosses a limit should lead to the same chain:
- Record the reading against the asset, with the date and the measurement point.
- Over watch: shorten the check interval and line up parts and a window.
- Over act: raise a corrective maintenance work order with the reading, a photo and the as-found condition. Where you can, confirm it with a repeat reading or a second method, such as oil analysis alongside vibration.
- Plan the job into a window inside the remaining P-F time. That's planned maintenance, not a breakdown, even though the trigger wasn't on the calendar.
- Repair, and record what was found. Was the part really failing? What failure mode?
- Adjust the limit if it was a false alarm. If act-level readings keep leading to healthy parts, the limit is too tight or the method is inconsistent.
The work order is what turns a reading into maintenance. A reading in a notebook that nobody acts on is just monitoring. Our work order management guide covers how to keep the job moving once it's raised.
Condition-based vs predictive vs preventive maintenance
Sources draw the lines between these three differently, and some treat predictive maintenance as a type of CBM. The most useful line is this: CBM reacts when a reading crosses a limit. Predictive maintenance forecasts when it will.
| Preventive (time-based) | Condition-based | Predictive | |
|---|---|---|---|
| Trigger | Calendar or run hours | A reading crosses a limit | A forecast of when it will |
| Data needed | The interval | Readings, a baseline, limits | Continuous data and a model |
| What it tells you | It's time | It's deteriorating now | How long you have left |
| Setup effort | Low | Moderate | High |
| Best for | Age-related wear, no warning | Failures with a detectable warning | Critical assets with steady data |
Most plants run all three. The types of maintenance guide shows how they fit together, and our predictive maintenance guide covers the forecasting side. Once the trigger fires, CBM and predictive work are managed the same way: a job is raised, planned into a window, done, and its findings recorded. The difference is how early you hear about it.
Advantages and limits of condition-based maintenance
What CBM does well:
- You stop replacing healthy parts. A part that's still running well stays in, instead of coming out because the calendar said so.
- It catches random failures. Many failures aren't tied to age. A calendar can't catch them. A reading can.
- Repairs become planned work. You get warning, so the job happens at a planned stop with parts ready, not at 2am with the line down.
What it needs:
- A detectable warning. No warning, no CBM.
- Discipline on the route. A route that slips is the most common way CBM quietly dies, because readings that stop being taken don't raise alarms.
- Someone who knows what the reading means. A vibration number with no baseline and no one to interpret it is noise.
When CBM isn't the right choice
CBM is RCM's first choice when it works. It doesn't always work:
- No detectable warning sign. Many electronic failures happen with no measurable change beforehand. There's nothing to check.
- A P-F interval too short to act on. If the warning shows minutes before the failure, a route can't catch it. You need an installed sensor with an automatic trip, or a redesign.
- The checking costs more than the failure. A cheap, non-critical part with no knock-on effect isn't worth a route. Let it run to failure and keep a spare.
- A hidden failure. A standby pump or a protective device can fail unnoticed because it isn't running. A reading won't show that. It needs a failure-finding test.
For those cases, the answer is preventive maintenance on a schedule, a failure-finding test, or deliberate breakdown maintenance (run to failure). The RCM decision logic is the structured way to choose.
Where a CMMS helps
CBM lives or dies on two things: the route getting done, and readings that cross a limit becoming work. A CMMS doesn't take the readings for you. Its job is to get the route out on time, put the limit in front of the technician, and turn the finding into a work order with a record behind it.
In MachDatum, an inspection route is a PM plan on a recurrence schedule with a versioned checklist attached. On the scheduled date, the inspection work order is created and assigned automatically, with the checklist already on it. Checklist steps can use option-type answers (for example "within limit", "over watch", "over act") and step instructions with photos, so every technician records the result the same way. Overdue routes surface in the PM list, and escalation rules pull in the maintenance manager when a job runs past its time threshold.
The limits can live on the asset itself. Custom asset attributes support numbers with units, so the baseline, watch and act levels for each machine sit on its record. The technician scans the asset's QR tag on the route and sees them on the spot.
When a reading is over the limit, the technician raises a corrective work order against the asset from the mobile app, with a photo of the as-found condition. Work order workflows can require fields before a job moves on, such as the reading and the as-found condition, plus the failure mode and root cause. At the next review, that history shows which assets the route is catching, and MTBF and MTTR by asset in analytics show whether breakdowns are falling.
If your machines are monitored with ThingConnect, MachDatum's sister product, condition signals such as cutting load drifting out of range can raise a condition-based trigger in MachDatum, and reason-coded stops open corrective work orders automatically. That applies to ThingConnect-connected CNC machines. See how the ThingConnect CMMS integration works.
We're onboarding our first group of manufacturing teams now. If your inspection readings live on clipboards and the follow-up depends on someone remembering, see how MachDatum CMMS handles PM plans, checklists and work orders.